A RESEARCH PROJECT IN 3D VISION

DGSfMDepth-Guided Scale-Aware
Global Structure-from-Motion

A monocular geometry as a scalable prior for global SfM.

MonoDepth → Scaled Relative Pose → GLOMAPSCROLL TO EXPLORE ↓

RECONSTRUCTION EXPLORER

Semi-Dense Point Cloud. Accurate Cameras.

Interactive 3D
POINT CLOUD VIEWER
RECONSTRUCTION DEMO

Scene

Loading the 3D viewer…

Drag to orbit · Scroll to zoom · Right-drag to pan
No camera poses loaded.

Synthetic architectural geometry demonstrates the viewer. This is not a DGSfM result.

Local files stay in your browser. Touch: one finger to orbit, two to zoom or pan. Keyboard: focus the viewer and use arrow keys to orbit, +/− to zoom.

01 / OVERVIEW

Bringing depth into the picture.

A global view of geometry,
with depth as a guide.

DGSfM reconstructs a scene from an unordered image collection. It combines monocular depth, local or dense image correspondences, depth-aware relative pose estimation, and scaled-depth guided global optimization to produce a COLMAP-format reconstruction.

Project overview based on the implementation. The paper abstract will be added with the publication.

01

Depth-guided geometry

Monocular depth provides geometric information alongside image correspondences.

02

Scale-aware optimization

Scaled-depth constraints guide global optimization of the reconstruction.

03

Scaled reconstruction

A COLMAP model with a common reconstruction scale via metric depth.

02 / THE METHOD

A path from pixels to structure.

Local observations.
Globally consistent geometry.

  1. 01 / INPUT

    Image collection

    Unordered views of a scene.

  2. 02 / PRIORS

    Depth & correspondences

    Monocular depth and sparse or dense matches.
  3. 03 / GEOMETRY

    Relative poses

    Depth-aware pose estimation and view-graph filtering.
  4. 04 / OPTIMIZATION

    Global reconstruction

    Scaled-depth guided optimization and COLMAP export.
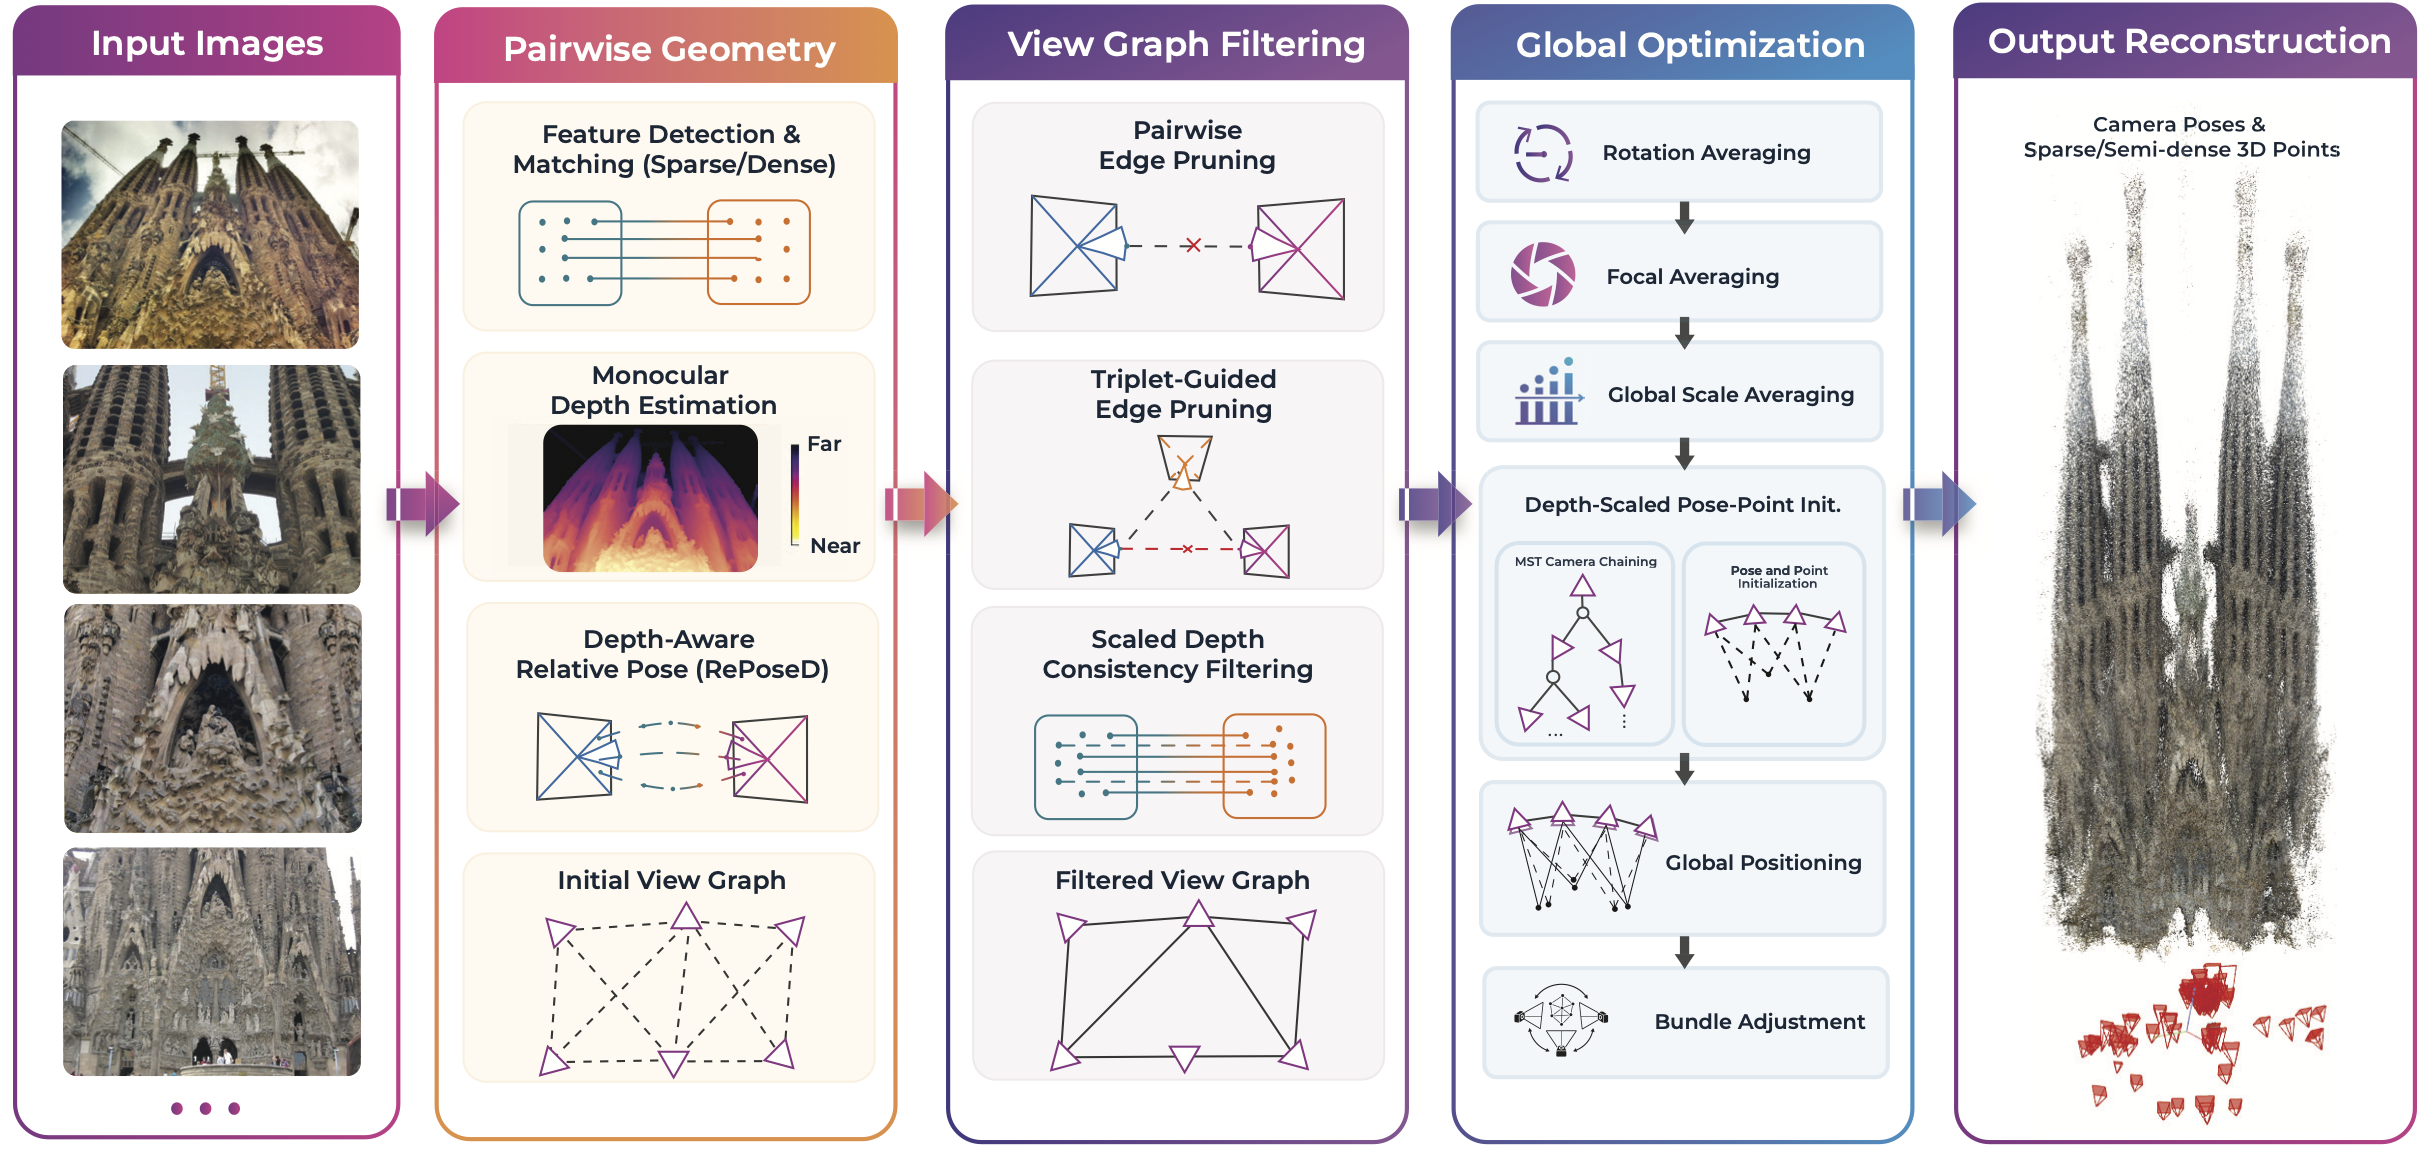
DGSfM pipeline: depth-aware relative pose estimation, view-graph filtering, global scale averaging, depth-guided pose-point initialization, global positioning, and bundle adjustment
The DGSfM pipeline. Figure 2 from the paper ↗

03 / RESULTS

Reconstruction, in a little more detail.

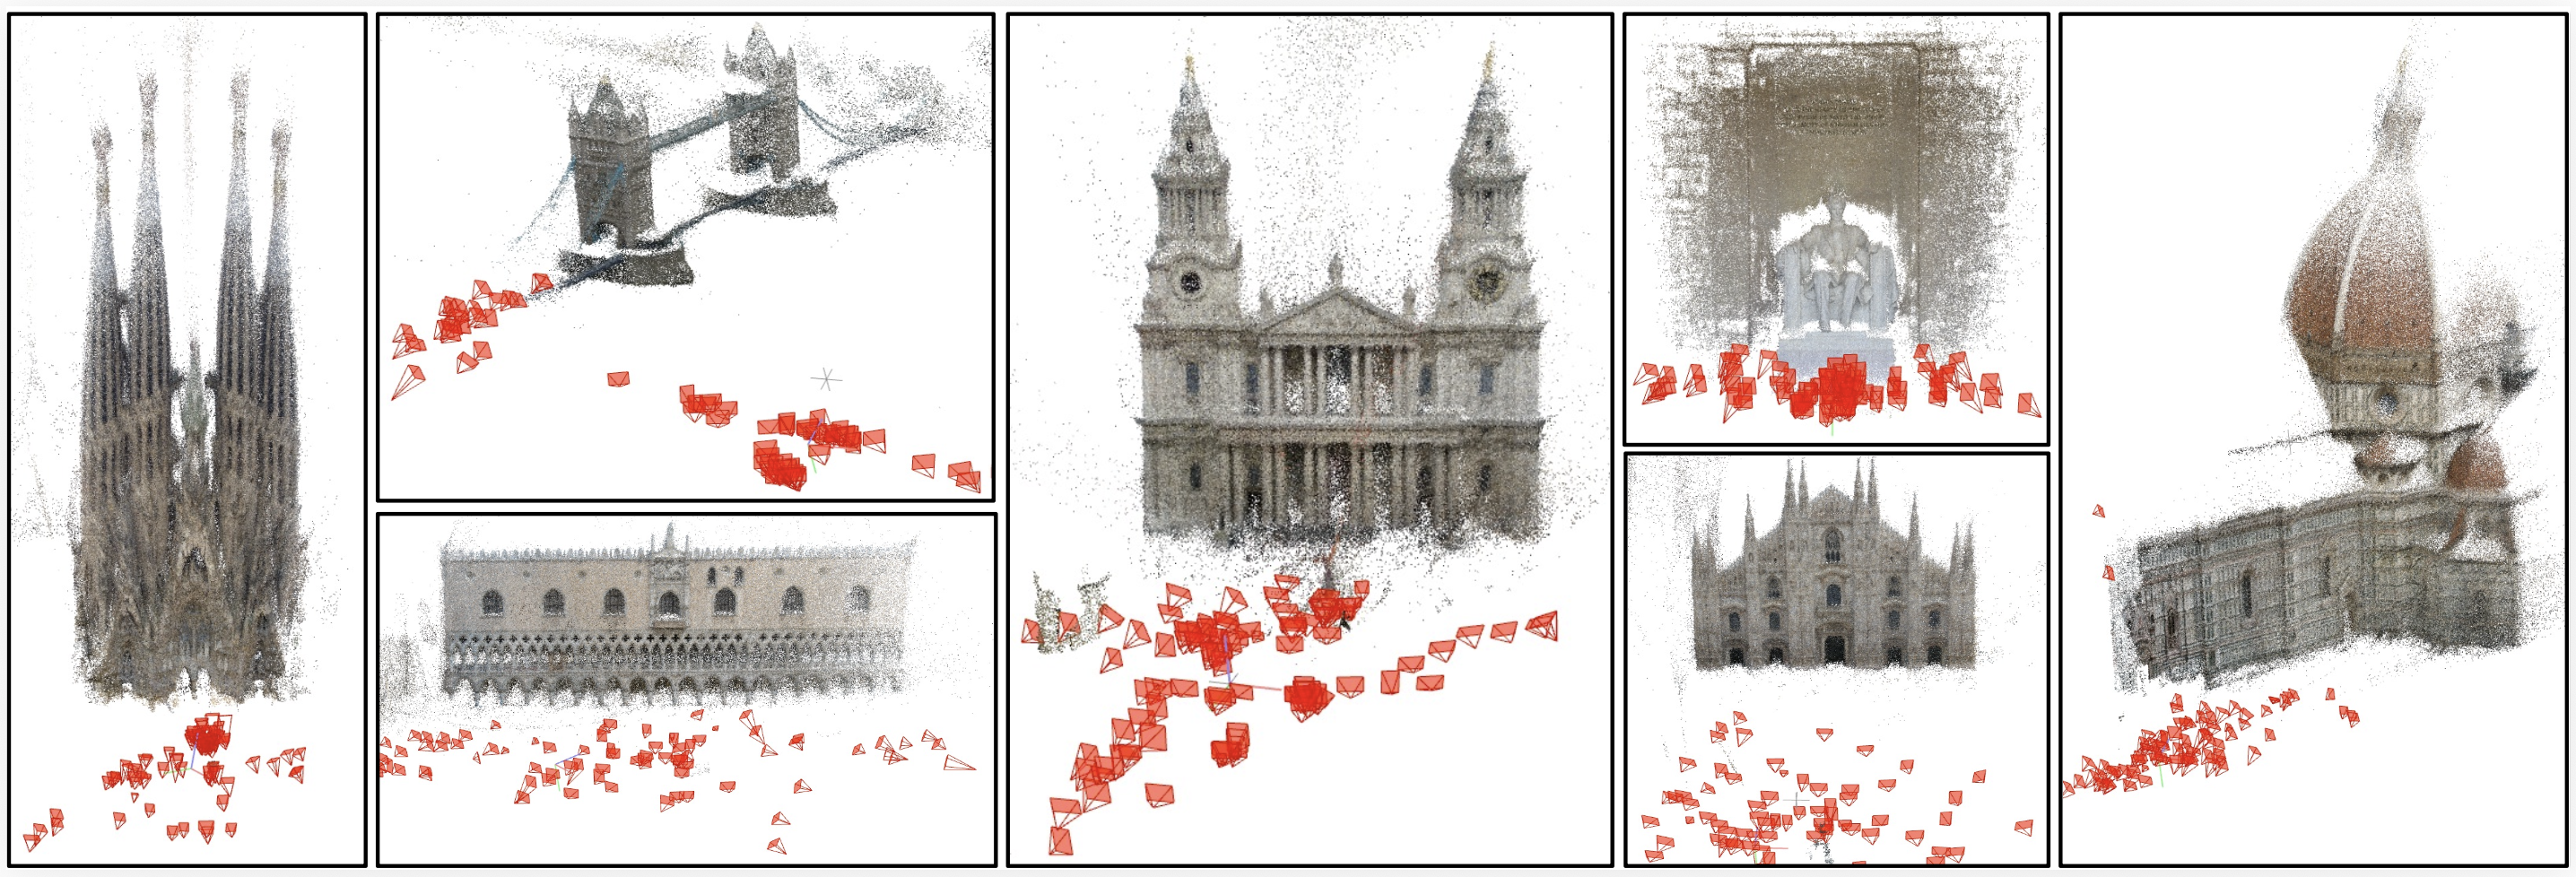
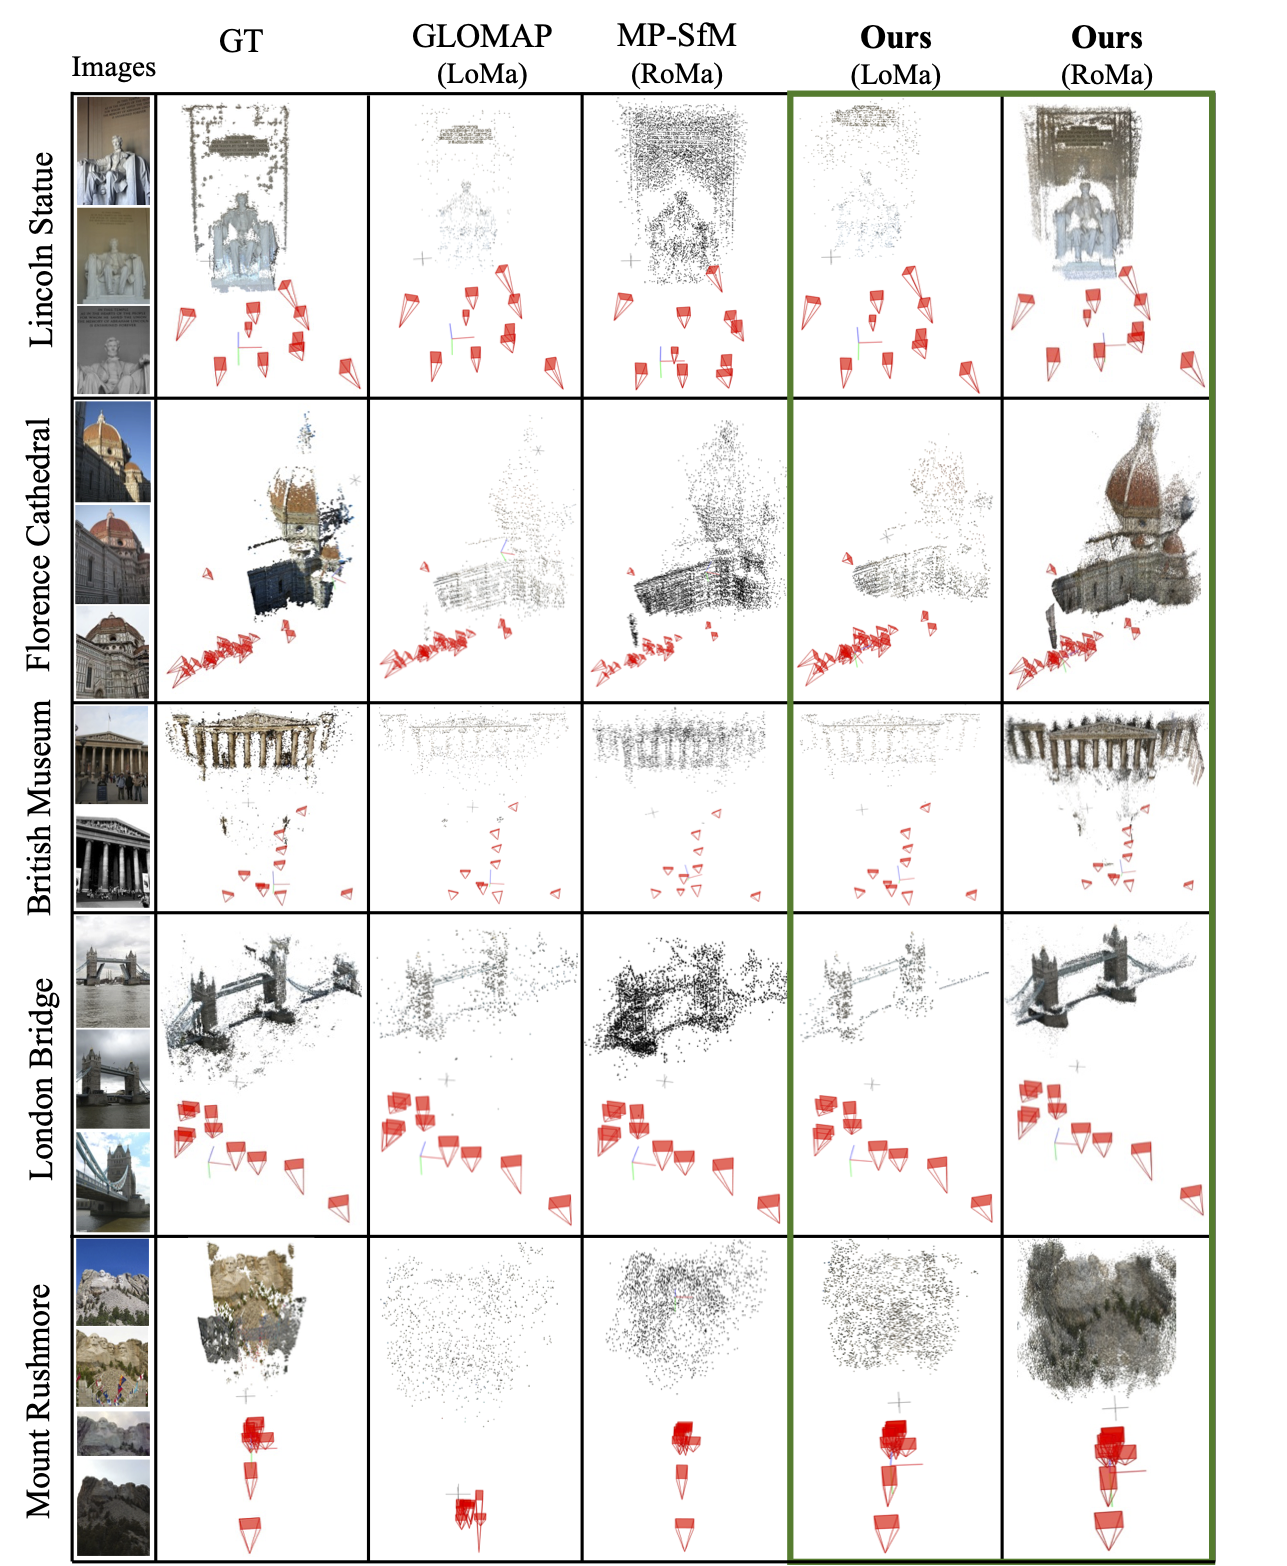
DGSfM reconstructions using RoMa matches on full image sets from IMC2021
From image collections to 3D. DGSfM reconstructions using RoMa matches on IMC2021. Figure 1 from the paper ↗
Qualitative reconstruction results from the DGSfM paper on ETH3D
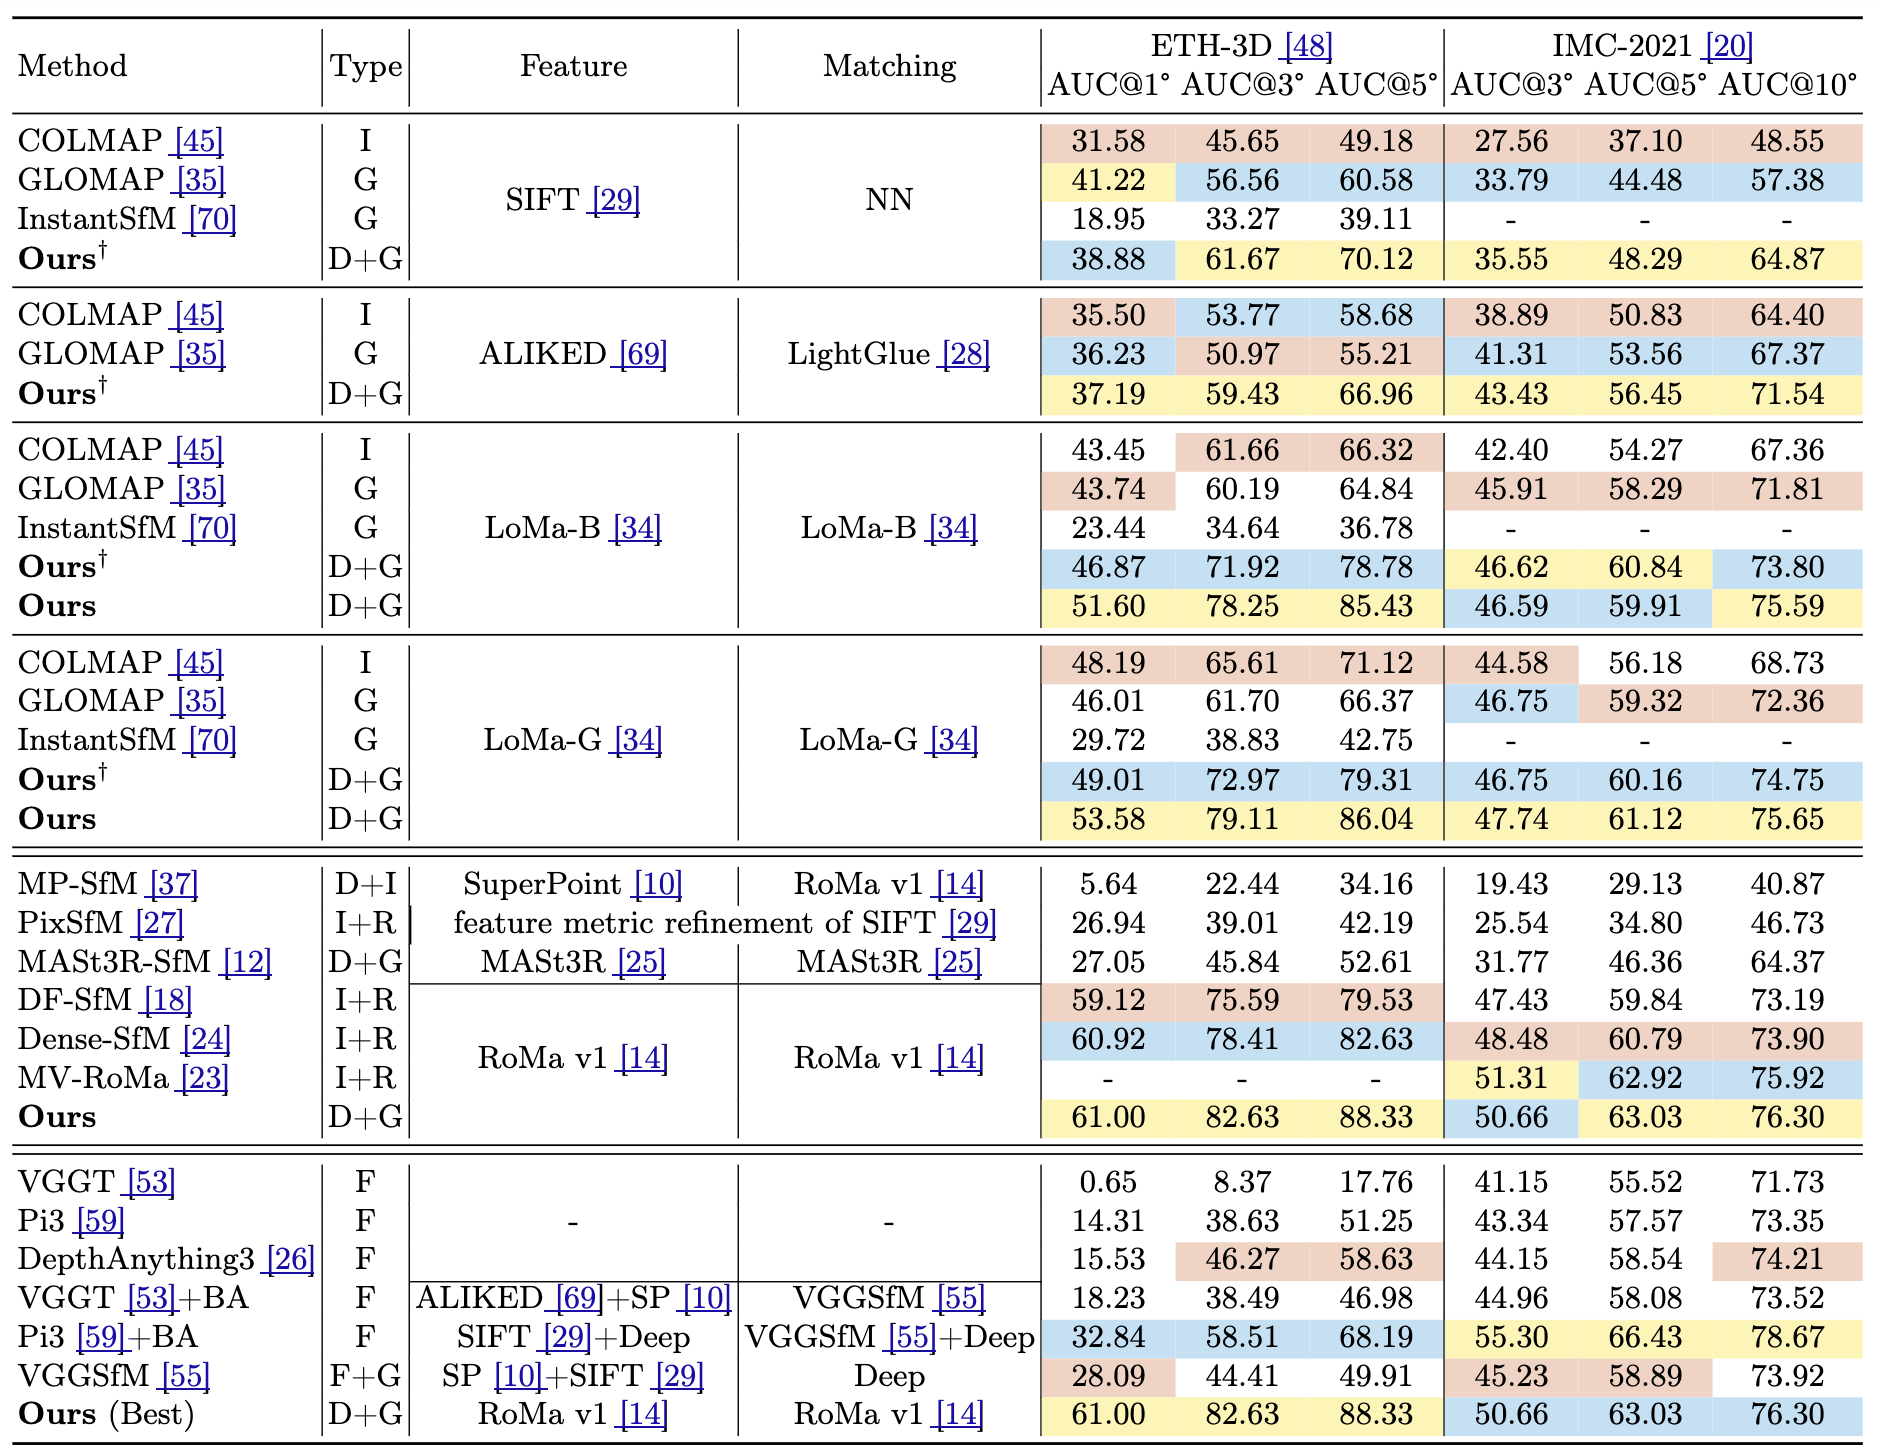
Multi-View Camera Pose Estimation on ETH-3D and IMC-2021. Compare against traditional SfM (incremental (I) and global (G)), feature refinement and dense-matching-based methods (R), monodep-based approaches (D), and feed-forward 3D reconstruction approaches (F) across different feature and matching front-ends. Table 1 from the paper ↗
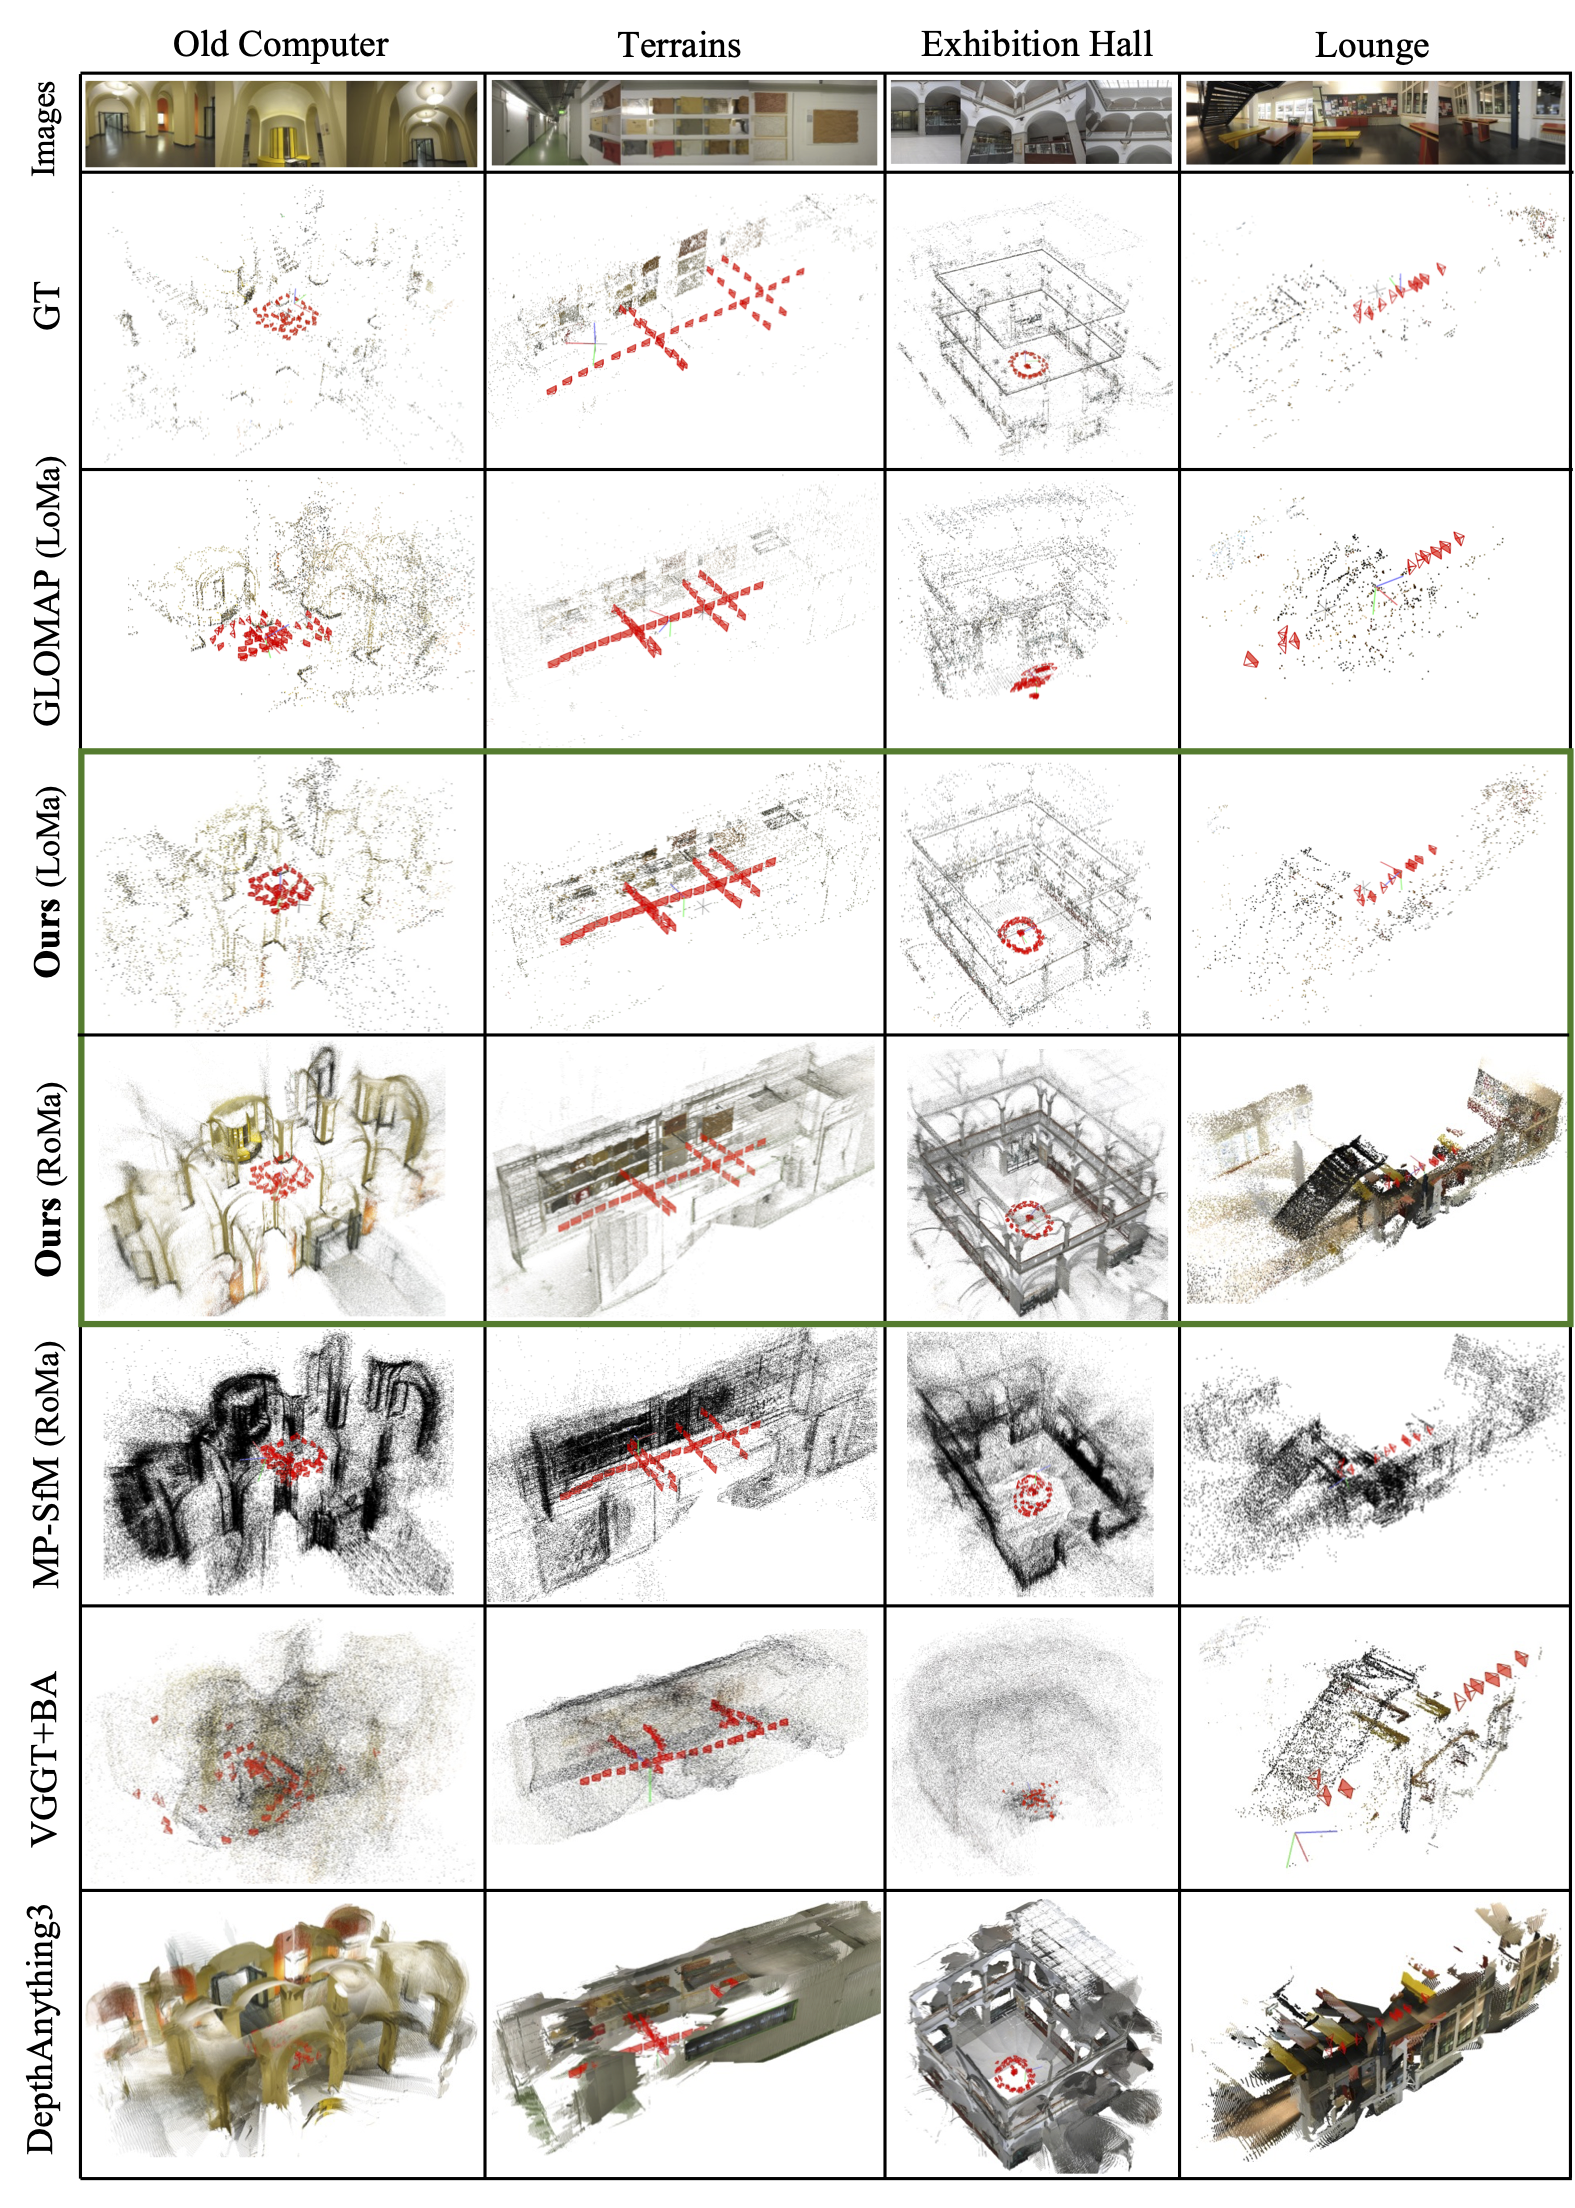
Qualitative reconstruction results from the DGSfM paper on ETH3D
Qualitative comparison on ETH3D indoor scenes.
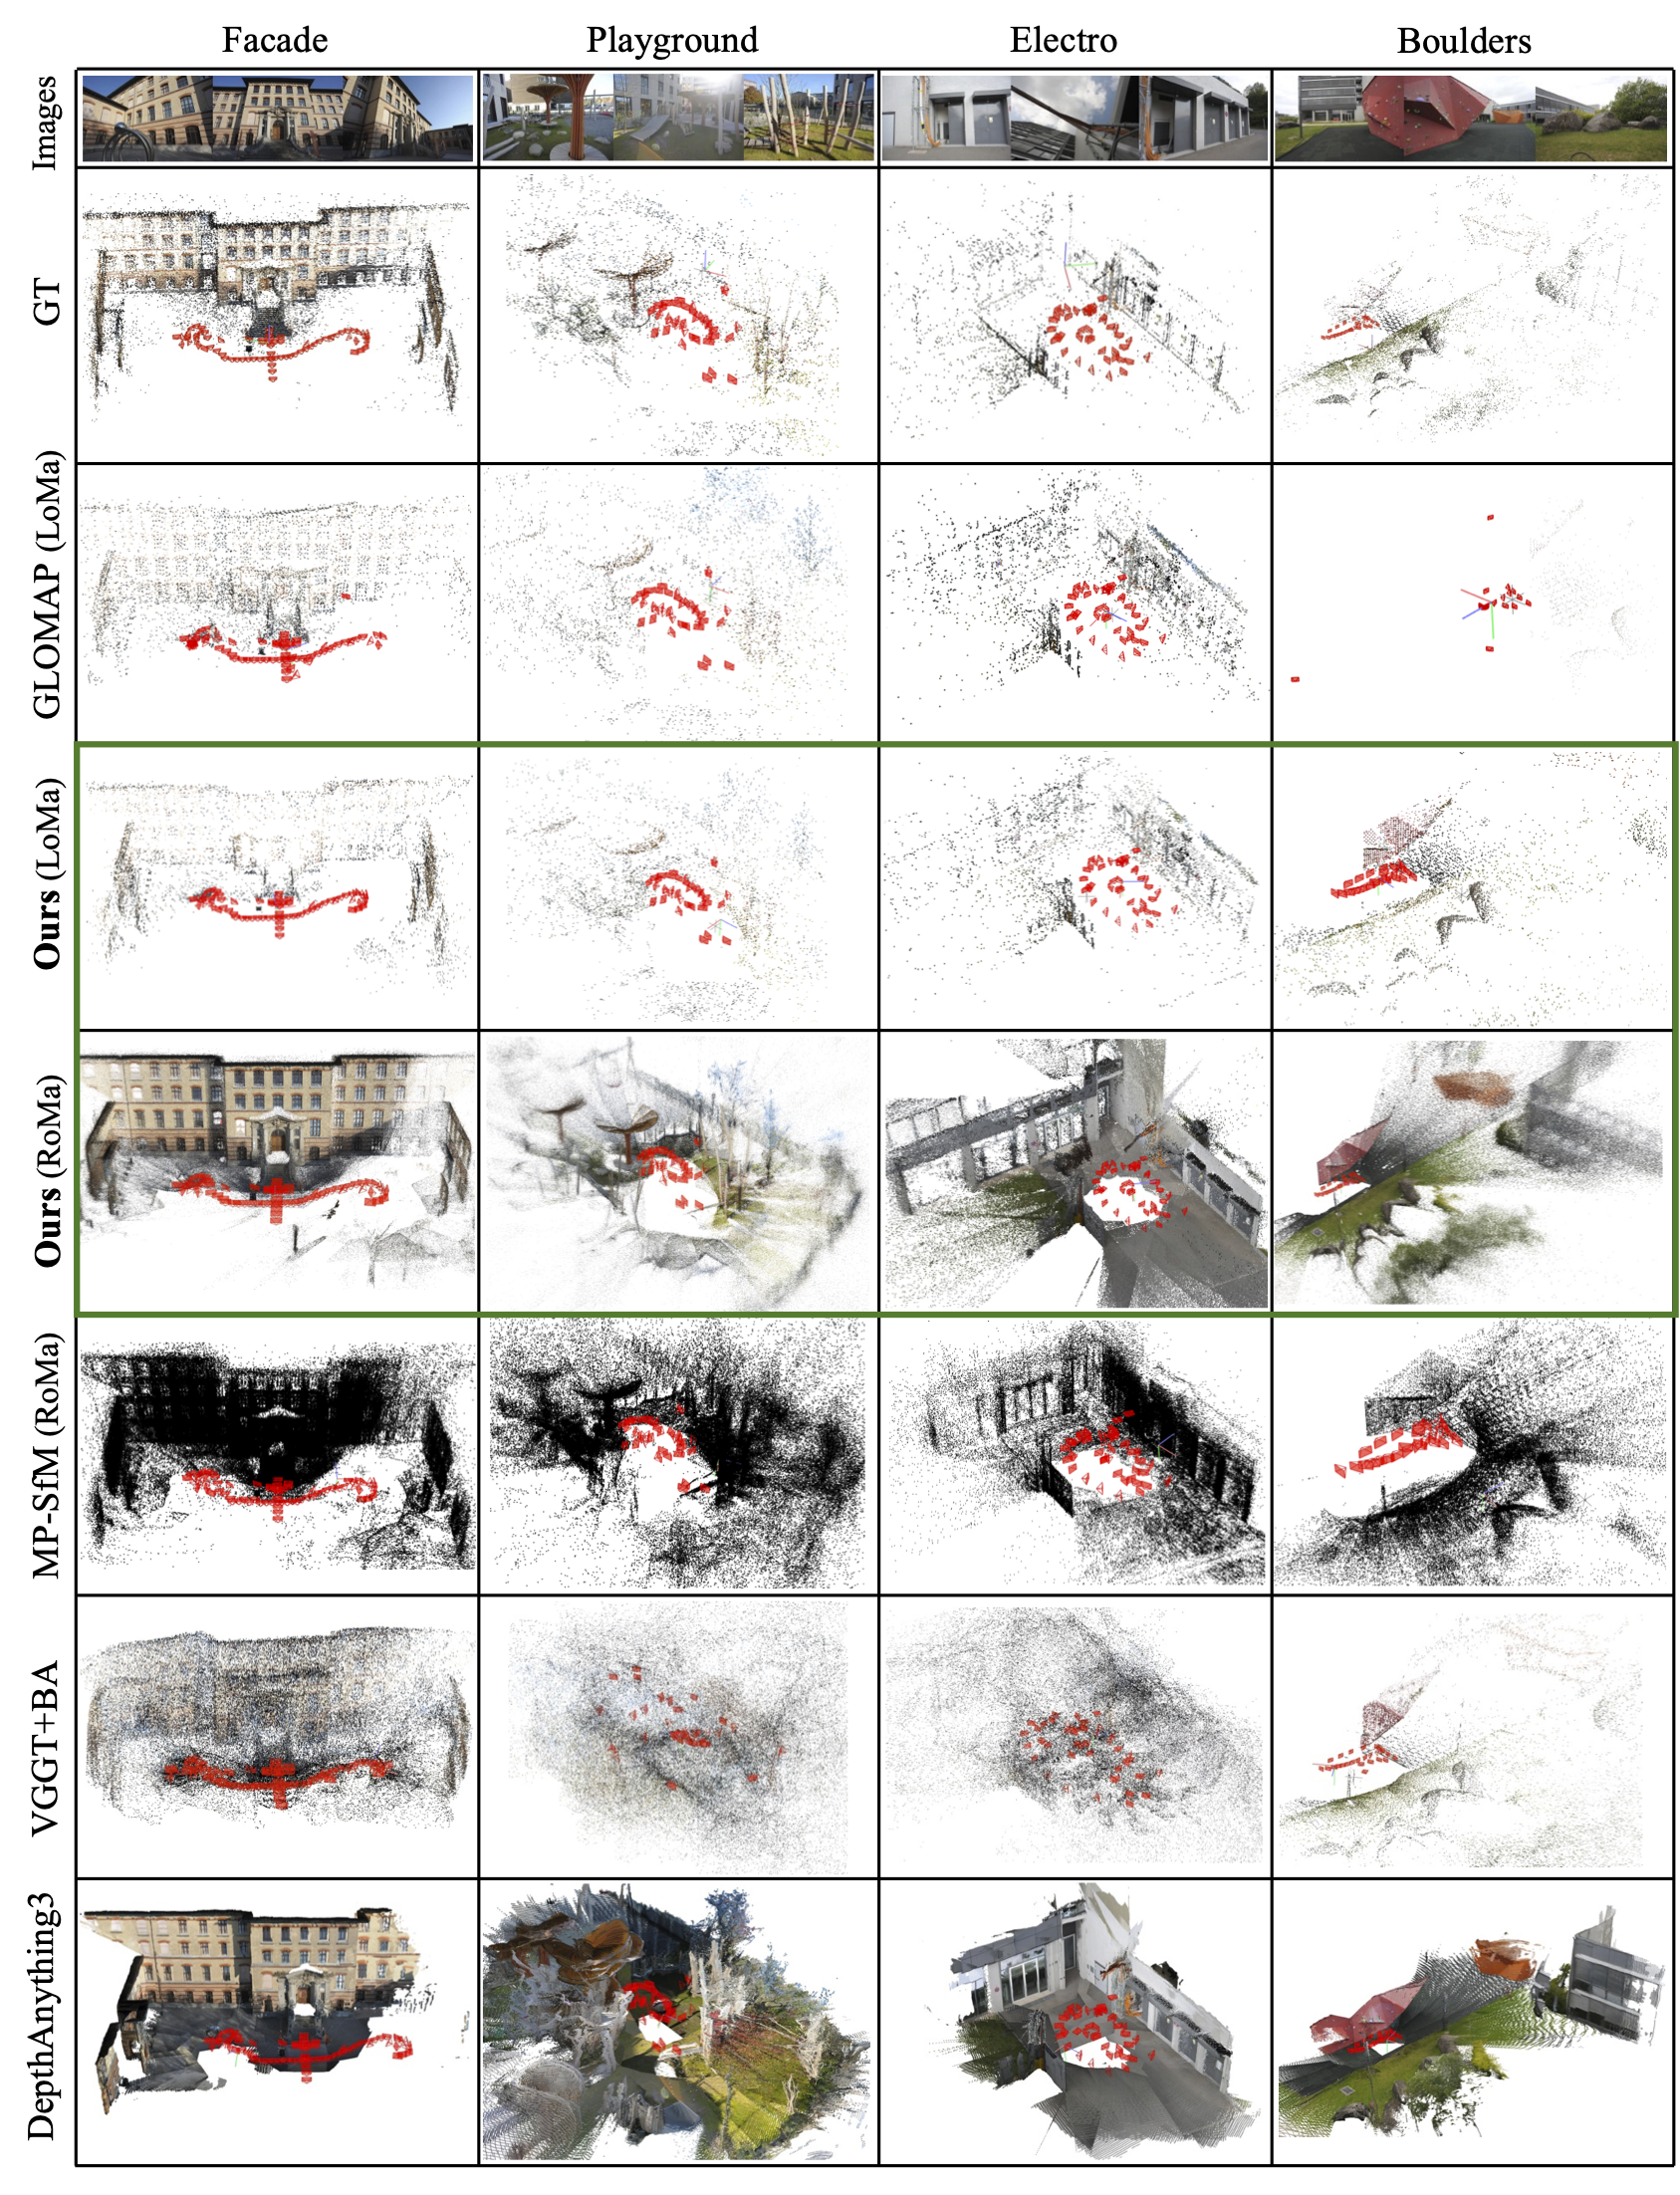
Qualitative reconstruction results from the DGSfM paper on ETH3D
Qualitative comparison on ETH3D outdoor scenes.
Qualitative reconstruction results from the DGSfM paper on ETH3D
Qualitative comparison on IMC2021 scenes with different image bags.

04 / REFERENCE

Build on this work.

Publication details and the paper citation will be added here.

Explore the code ↗